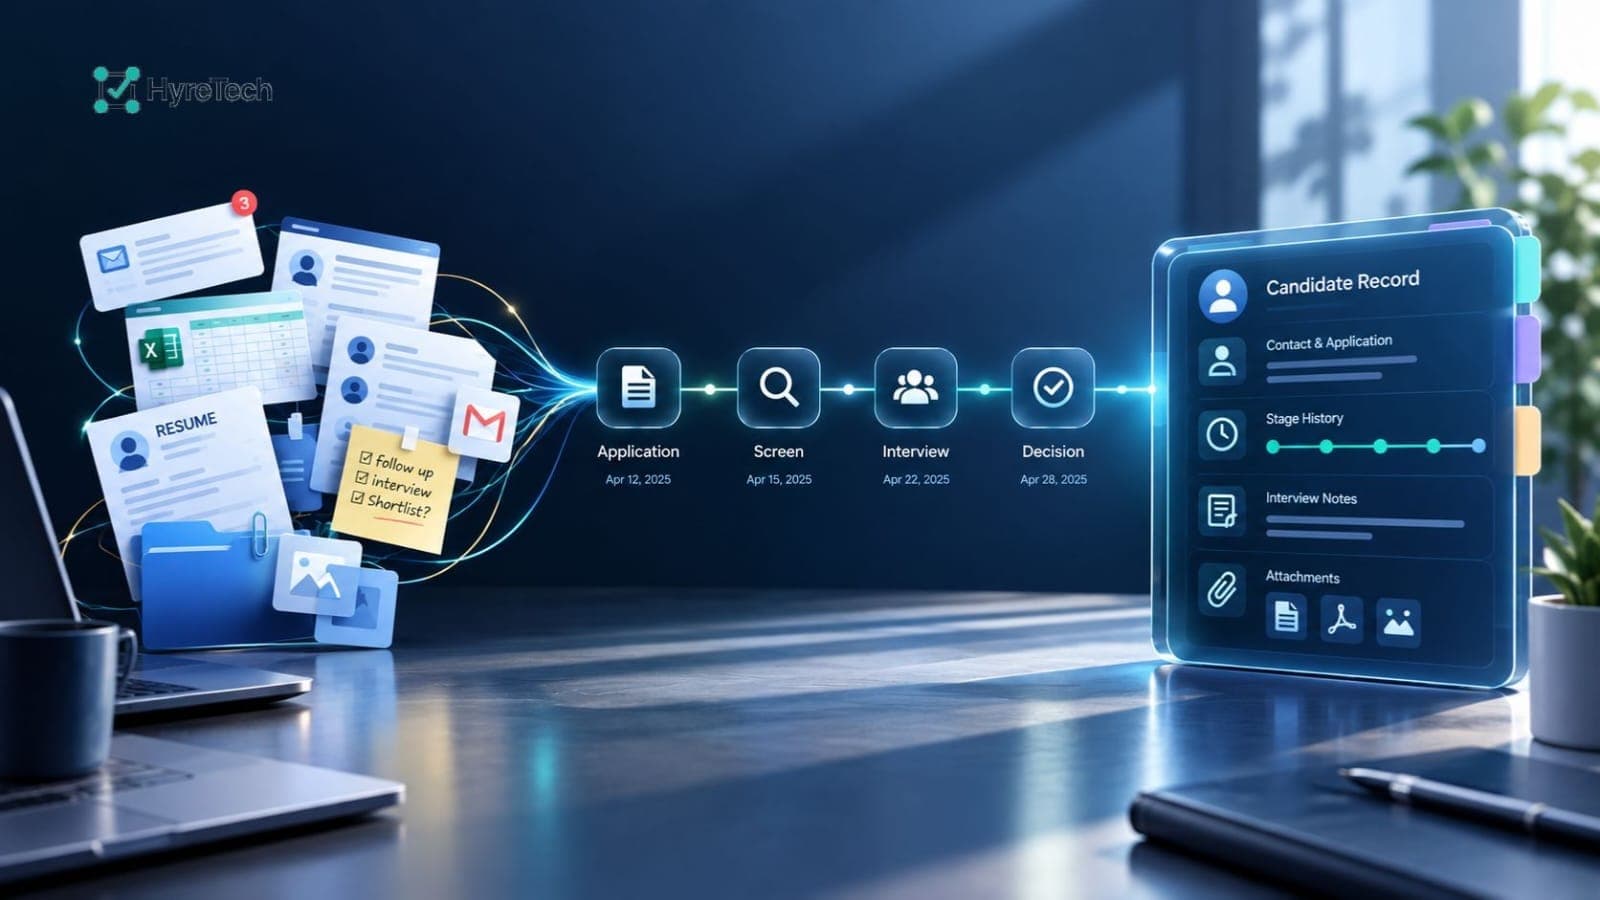
A spreadsheet-and-email hiring process usually breaks down not because it's low-tech, but because nothing enforces structure: notes live in someone's inbox, the "latest" version of the tracker depends on who saved last, and there's no record of when a candidate moved from one stage to the next. A simple ATS that lets you move off email and Excel without losing your candidate database needs to preserve four things a spreadsheet can't reliably hold onto: structured contact and application data, a timestamped stage history, interview notes tied to the right person, and a defined policy for deleting candidate data. Not just more columns.
If you're hiring through email threads and a shared Excel or Google Sheets tracker, you already know where it breaks: a candidate replies to the wrong thread, someone updates the tracker on their laptop and forgets to sync it, and by the time there are 40 applicants for one role, nobody's sure which row is current.
This isn't a discipline problem. It's what happens when a process needs structure that a spreadsheet was never built to enforce.
What Actually Breaks First
Version conflicts
Two people edit the same sheet, and the "true" state of a candidate depends on whose edit was last, not what's actually accurate.
Notes scattered across inboxes
Interview feedback lives in whoever's email happened to receive it, not attached to the candidate record itself. It disappears when that person is out, or just forgets to forward it.
Overwritten history
Updating a “Status” cell erases the previous status. Six weeks later, nobody can say when a candidate was screened, or how long they sat in each stage.
Attachments live outside the row
Resumes, portfolios, and take-home assignments end up in a separate folder structure that inevitably drifts out of sync with the row that's supposed to reference them.
Duplicates
The same person applies twice, or gets added by two teammates, and the sheet has no way to know they’re one applicant.
What a Real Candidate Database Needs to Preserve
Structured contact and application data
Not just name and email, but which role, which source, and application date, in fields that can be searched and filtered rather than read one row at a time. Deduplicated on email, so one person is one record.
A timestamped stage history
Not just a candidate's current status, but when they moved from each stage to the next. This is what a spreadsheet almost never captures, because updating a status usually means overwriting it, not logging it.
Interview notes attached to the right person, not the right inbox
Feedback needs to live on the candidate record itself, tied to who wrote it and when, not float in a thread that only one person can find later.
A defined deletion policy
Candidate data shouldn't sit indefinitely just because deleting a spreadsheet row feels irreversible. You should know how long unsuccessful applications are kept, and be able to delete a candidate, a role’s data, or everything, and have that deletion actually happen.
Under Singapore’s PDPA, keeping personal data longer than the purpose requires contravenes the Retention Limitation Obligation, and a shared file nobody owns is exactly how that happens.
Two things are worth wanting but rarely come with a lightweight tool, ours included: a full audit trail of who_viewed_each_candidate’s data, and per-tenant retention rules that auto-delete on a schedule.
If your compliance team requires those, put them on the checklist before you choose, rather than assuming any candidate database has them.
What your Spreadsheet Columns Actually Become
Most hiring spreadsheets already have something close to the right columns. The problem isn't the data, it's that nothing enforces what happens to it. Here's roughly how a typical spreadsheet maps onto a structured candidate database:
| Your spreadsheet column | What it becomes |
|---|---|
| Name, email, phone (free text) | Structured contact fields: searchable, and deduplicated on email |
| "Role" or "Position" column | A link to the actual role record, so one candidate can sit in several pipelines |
| "Status" column, manually updated | A stage history: every change timestamped, not overwritten |
| A "Notes" column everyone edits | Notes and scorecards per candidate, attributed to whoever wrote them |
| A folder of resumes named by hand | Resumes parsed and attached directly to the matching record |
| A "Source" column (if you have one) | Structured source, so you can finally see which channel produces hires |
Nothing here requires re-entering data from scratch. It's closer to re-pointing columns you already have at fields that actually hold onto their history.
Why This is More Than a Tidiness Problem
Hiring records aren't purely operational. In most jurisdictions, there's some obligation to keep records related to a hiring decision for a defined period, and an obligation not to keep personal data longer than that.
If you're hiring in or into Singapore the PDPA’s retention limitation obligation applies to every applicant row in your sheet: you may keep it only as long as it serves the purpose it was collected for, and you have to be able to show what you hold and delete it on request. A shared spreadsheet with copies in three inboxes makes both of those hard. How PDPA applies to AI-assisted hiring covers the specifics.
The same shape applies elsewhere. SHRM's summary of U.S. federal record retention requirements lists job applications, screening tools and interview materials among records employers need to be able to produce, and Australia and New Zealand each have their own employment-record and privacy rules. The specifics differ. The underlying problem is the same everywhere: a spreadsheet with overwritten history and no deletion policy makes it much harder to demonstrate what actually happened during hiring.
How Long Switching Actually Takes
The usual reason teams put this off isn't disagreeing that spreadsheets are a problem. It's assuming the fix means re-entering everything by hand. For a spreadsheet that's already reasonably organized (one row per candidate, consistent columns), importing it into a structured database is closer to uploading the file and mapping columns once than rebuilding anything.
Concretely, HyreTech's importer needs four columns: name, email, a reference to the role, and the resume filename. Everything else is optional, and unknown columns are ignored rather than rejected, so you don't have to clean the sheet first. Applicants are matched on email within a role, so uploading the same sheet twice doesn't create duplicates. The applicants CSV reference lists every column we read.
The work that actually takes time is deciding what your stages should be called and who on the team should see what. Not moving the data itself.
If you're not Sure you Need a Full ATS yet
Not every team tracking candidates in a spreadsheet is ready for a full applicant tracking system with postings, pipelines, and offer letters.
If the actual pain point is just "I can't keep candidate data straight anymore," a lighter step is importing what you already have into a structured candidate database and building from there, without committing to overhauling your whole hiring process at once. See how the import path works.
If you're already on a full ATS like Greenhouse and want to switch systems rather than move off spreadsheets entirely, our Greenhouse migration guide covers that instead.
Ready to Move off The Spreadsheet?
If you want to try it on your current pipeline: Start free and import your existing candidate spreadsheet directly. No need to re-enter anything by hand.
If you're not sure whether a full switch makes sense yet: Book a demo and we'll look at your current process together before you commit to anything.
FAQ
1.Is there a simple ATS to move off email and Excel without losing our candidate database?
Yes. Any tool with a CSV import can take a one-row-per-candidate sheet. What you're checking for is whether it keeps the history the sheet was losing: a stage timeline rather than an overwritten status, notes on the candidate record rather than in email, and one record per person. HyreTech imports a spreadsheet with four required columns and matches applicants on email, so the move is an upload and a column mapping, not a re-entry.
2.What's wrong with using a spreadsheet to track job candidates?
Spreadsheets don't enforce structure: stage history is overwritten rather than logged, notes tend to live in email rather than attached to the candidate, duplicates go unnoticed, and there's no defined point at which old applicant data gets deleted. None of this is a discipline problem. It's what happens when a process needs more structure than a spreadsheet is built to provide.
3.What should a candidate database include at minimum?
Structured contact and application data deduplicated on email, a timestamped history of stage changes (not just current status), interview notes attached to the right candidate record, and a defined policy for deleting unsuccessful applications.
4.Do I need a full ATS to fix this, or is there a simpler option?
Not necessarily. If the core problem is keeping candidate data organized and searchable, importing your existing spreadsheet into a structured database is a smaller step than adopting a full applicant tracking system with postings and pipelines.
5.How long should hiring records be kept?
It depends on your jurisdiction. Under Singapore's PDPA, personal data may be kept only as long as it serves the purpose it was collected for. In the U.S., federal guidance generally expects employers to be able to produce applications, screening results and interview materials for a defined period after a hiring decision. Australia and New Zealand have their own rules. Check local requirements rather than assuming.
6.How long does it take to move from a spreadsheet to a candidate database?
If your spreadsheet already has one row per candidate with reasonably consistent columns, moving it is closer to uploading the file and mapping columns once than re-entering data by hand. The part that takes time is deciding on stage names and access permissions, not migrating the data.