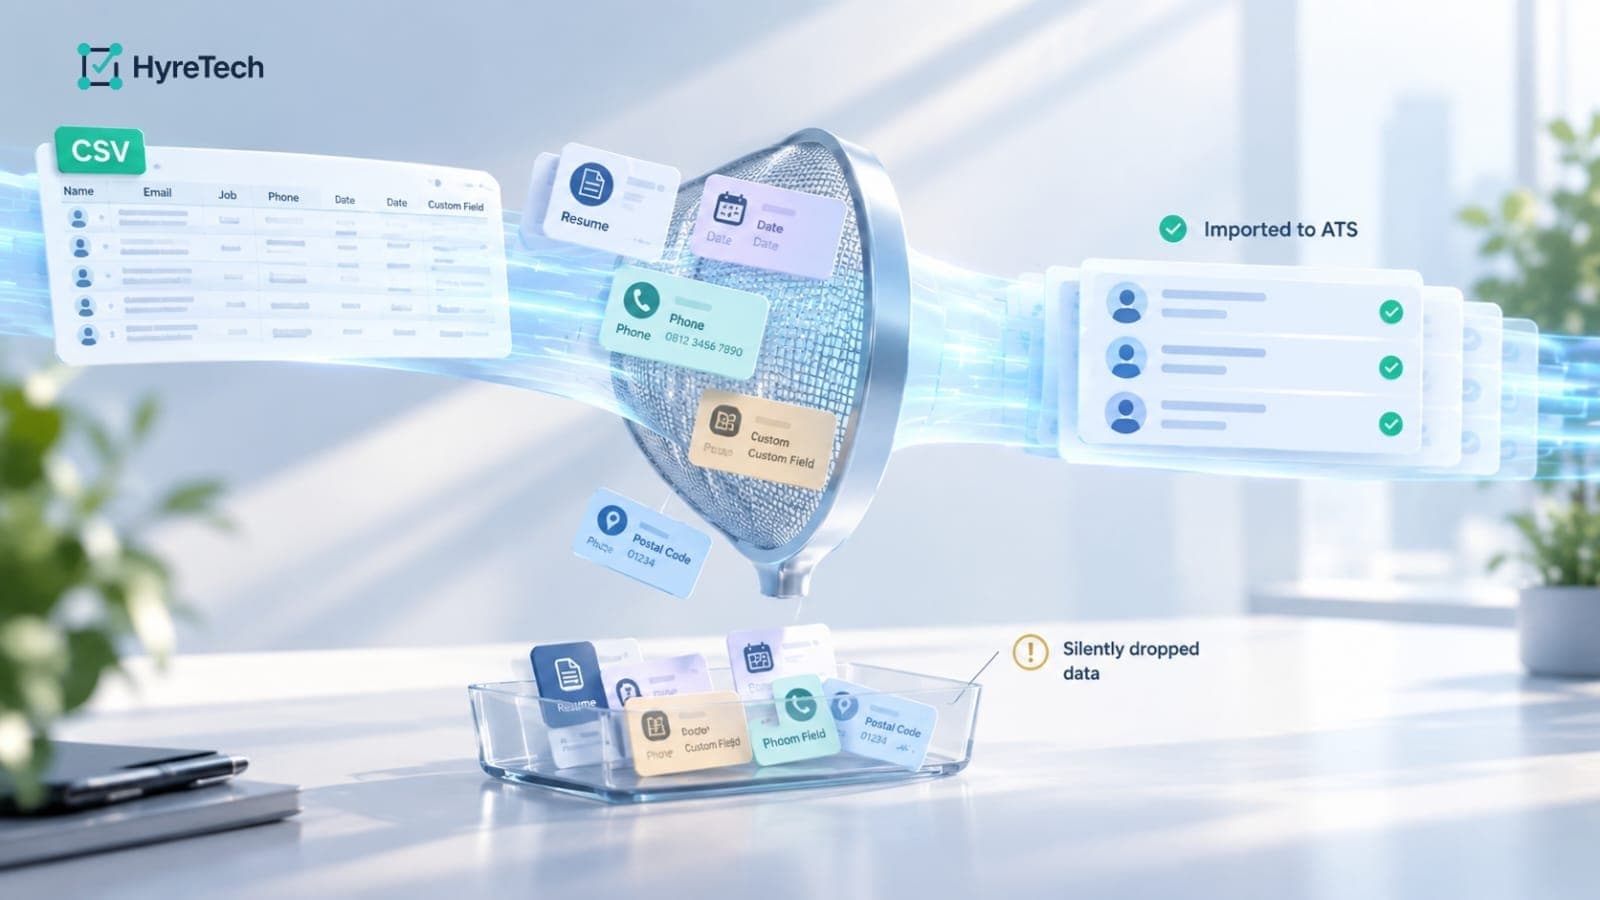
The most damaging CSV import failures aren't the ones that throw an error. They're the ones that succeed with missing data and no warning. The most common silent drops are: resumes that fail to attach because the email column was left blank, candidates that never import at all because their job wasn't mapped, dates that get corrupted because a spreadsheet program reformatted them before upload, postal codes and phone numbers that lose their leading zeros the same way, and custom fields with no equivalent in the destination system that simply vanish. None of these produce an error message. You only find out when someone notices a candidate's history looks incomplete, usually weeks later.
An import that "succeeds" isn't the same as an import that's complete. A CSV file can upload cleanly, map every column, and finish without a single error, and still be missing information that mattered, because CSV import tools are built to move data that fits the format, not to flag data that got quietly left behind. The dangerous part isn't the failure. It's that there isn't one.
The checklist below applies regardless of which system you're importing into, including HyreTech's own CSV import, whether you're bringing candidates in from a spreadsheet or from another ATS.
If you're still building the file, start with what the CSV needs and come back here before you upload it.
The Five Silent Drops at a Glance
| What goes missing | Why there's no error | The fix | What HyreTech does |
|---|---|---|---|
| Resumes, when the email column is blank | The candidate record is still valid without a resume | Fill an email on every row that has a resume | email is required. A blank one skips the row and reports it |
| Every candidate on an unmapped job | The tool treats an unmapped job as excluded on purpose | Map every job, including closed and renamed ones | A role reference with no match is reported row by row |
| Dates | The spreadsheet rewrote the value before upload | Set the column to Text, then enter YYYY-MM-DD | The applicants file has no date columns to corrupt |
| Leading zeros in postal codes, phones and IDs | The spreadsheet stored the value as a number | Set the column to Text before entering data | Stores what the file contains, so fix it in the spreadsheet |
| Custom fields with no destination match | An unmapped column counts as intentionally left out | Decide which fields matter and map them by hand | Unknown columns are ignored, not rejected |
The CSV Columns an ATS Import Silently Drops
Five specific failure points account for most of the data that goes missing during a CSV-based ATS import, each one because the tool has no way to distinguish "intentionally left out" from "lost."
1.A missing email breaks resume attachment
According to Greenhouse's own documentation on bulk candidate import, the email column isn't required to import a candidate record, but if resumes are being uploaded as part of that import, an email address is what maps each resume file to the right candidate.
Leave the email column blank, and the candidate record can still be created successfully. The resume just doesn't attach to it. The import shows as complete. The candidate just has no resume, and nothing in the process tells you why.
HyreTech's own import handles this differently, worth knowing either way: email is one of four required columns (alongside name, external_role_id and cv_filename), so a row with a blank email is skipped and reported upfront rather than producing a resume-less record after the fact.
2.Unmapped jobs mean the candidate never imports
Every job listed in an import spreadsheet has to be mapped to an actual job in the destination system during setup. Per Greenhouse's own import process, candidates linked to a job that wasn't mapped are not imported at all, not "imported with a missing field," but skipped entirely.
If a spreadsheet references a role that was renamed, closed, or simply typed differently than the destination system's job title, every candidate tied to that row disappears from the result with no per-row error to flag it.
This is the one drop where tools differ most, so test it before you trust an importer. On HyreTech, an applicant whose external_role_id has no match in the roles file is still skipped, but it is not silent: the row is listed in the batch report with the value that failed to match, and the batch finishes as Partial instead of Completed.
3.Dates get reformatted before they're even uploaded
This one usually happens before the import tool ever sees the file. Spreadsheet programs auto-format date-like text, and a value like a stage-change date can get silently rewritten into a different date, a different format, or occasionally a serial number, depending on the program's locale settings, all before the file is uploaded anywhere.
Greenhouse's own guidance for this exact problem is to enter dates in YYYY-MM-DD format and set the column format to Text before typing anything in, specifically so the spreadsheet editor doesn't "helpfully" reformat it first.
Once a date's been silently rewritten, the import tool has no way to know the value it received wasn't the original.
4.Leading zeros disappear from IDs, postal codes, and phone numbers
The same auto-formatting behavior that corrupts dates does the same thing to any field that looks numeric but isn't meant to be treated as a number.
This one is easy to miss precisely because it's so common in this market: Singapore postal codes are six digits and often start with a zero, "018956," for instance. Typed into an unformatted spreadsheet cell, that becomes "18956," because a spreadsheet program reads it as the number 18956, and numbers don't keep leading zeros. Phone numbers go the same way: an Indonesian mobile entered as "0812…" loses its zero, and a "+65…" or "+62…" number can lose its plus sign. Internal candidate IDs are just as exposed.
The fix is the same as for dates: set the column to Text format before entering the data, not after. Reformatting a column after the zeros are already gone doesn't restore them. No importer can repair this one, ours included, because the file it receives already contains the wrong value.
5.Custom fields with no destination match
Every ATS has a set of standard fields it expects: name, email, job, source, and a handful of others. Anything outside that standard set (an internal priority tag, a custom scoring note, a field specific to how one team tracks candidates) has to be manually mapped to an equivalent field on the other side.
If there isn't one, most import tools simply don't bring that column across. There's rarely an error for this either, because from the tool's perspective, nothing went wrong: an unmapped column is treated as intentionally excluded, not as a mistake to flag.
HyreTech's own import works the same way here. Unknown columns are ignored rather than rejected, which is what makes a messy spreadsheet importable at all, but it also means a mistyped optional column, linkedin instead of linkedin_url for example, won't carry over, with nothing telling you it didn't.
A mistyped required column is the opposite case: every row fails with a missing-field message. The applicants CSV reference lists every column we read, required and optional.
The One Failure That Does Announce Itself
Not every CSV problem is silent. Open a very large export in Google Sheets as an intermediate step and you may hit a hard, visible refusal, because Google Sheets stops at 10 million cells per spreadsheet.
That is the easier problem to have: split the file into smaller batches by role or by date range. Importers have ceilings of their own. HyreTech's is 100 roles and 200 applicants per upload, and a file over that is refused outright rather than truncated.
A Pre-Import Checklist That Catches These Before They Happen
Before exporting
Confirm every row has an email address if resumes are being attached, even for candidates without an active application. What to export from Greenhouse, Lever, Workable or Ashby covers what each of the four actually hands you.
Before uploading
Set date columns and any ID, postal code, or phone number columns to Text format first, then re-enter the values in a fixed format. Reformatting after the fact doesn't recover data that's already been silently altered.
During job mapping
Map every job explicitly, including ones you think are closed or renamed. An unmapped job silently drops every candidate attached to it, not just the job listing itself.
For custom fields
Decide in advance which non-standard fields matter enough to manually map, and accept that the rest will not carry over, rather than discovering that after the fact.
After import
Spot-check a sample against the original file specifically for resumes attached, dates and ID numbers matching exactly, and candidates from less-common or renamed job titles. These are the places drops concentrate. Then count rows in the file against records created.
What HyreTech's Import Reports Instead of Dropping
HyreTech validates every row on its own, skips the bad ones, and reports each skipped row with its reason. The good rows still land, and the batch finishes as Completed, Partial or Failed, so "Completed" means every row made it.
These are the messages a skipped row carries:
- Missing required name, email, external_role_id, or cv_filename. One of the four required columns is blank on that row.
- External_role_id "…" not found in roles.csv. The applicant points at a role that isn't in the roles file.
- Resume "…" not found in the ZIP. The filename in the CSV has no matching file. Letter case is ignored, the extension is not.
- Resume "…" must be PDF. Word documents and images are skipped, not converted.
- Duplicate email+role in this import; skipped. Two rows share an email on the same role.
Because candidates match on email and roles on their ID, the repair is to fix the file and upload it again. Nothing is duplicated, and only the rows that changed are scored again. What happens when you upload the same batch twice has the edge cases.
What it will not catch is anything the spreadsheet altered before upload, or an optional column it doesn't recognise. Drops 3, 4 and 5 are yours to prevent, whichever tool you use.
Why This Connects to More Than Just Tidy Data
A dropped field isn't just an inconvenience. If you're required to retain accurate hiring records (a theme covered in what a candidate database needs to preserve), a silently incomplete import means the record you're keeping isn't actually complete, even though nothing flagged it as a problem. That gap matters more the longer it goes unnoticed.
This is also exactly why migrating candidate history from an existing ATS is worth treating as a checklist, not a single upload-and-done action. The failure mode isn't the import rejecting your file. It's the import accepting it with pieces missing.
Ready to Import Without The Guesswork?
If you want to see the scoring before you export anything: run one resume and one job description through the free resume screener. It takes two minutes and needs no account.
If you want to see what actually carries over: Start free and run a test import with a small batch of your own candidate data.
If you're migrating a large or messy dataset: Book a demo and we'll map your fields with you before anything gets imported for real.
FAQ
I just ran a CSV import into our ATS and it said "complete" with zero errors, but some candidates are missing resumes and others didn't show up at all. What's going on?
This is almost always one of two things, not a bug: a blank email column (which breaks resume attachment without blocking the import) or an unmapped job (which drops every candidate tied to that job with no per-row warning). Tools differ on whether they tell you. HyreTech lists every skipped row with its reason, so a batch with either problem finishes as Partial rather than Completed.
What CSV columns get silently dropped during an ATS import?
Five kinds of data: resumes on rows where the email column is blank, every candidate linked to a job that wasn't mapped, dates that a spreadsheet reformatted before upload, leading zeros in postal codes, phone numbers and IDs, and custom fields that have no equivalent field in the destination system.
Why doesn't a CSV import show an error when data is missing?
Because from the import tool's perspective, nothing went wrong. An unmapped custom field is treated as intentionally excluded, and a record with no resume attached is still a valid, successfully created record. The tool has no way to know data was lost unless the missing piece breaks a required field.
How do I stop dates and leading zeros from getting corrupted in a CSV import?
Set the column's format to Text before entering any values, and use a fixed date format like YYYY-MM-DD. Spreadsheet programs otherwise rewrite date-like and number-like values before the file is ever uploaded. If the zeros are already gone, reformatting the column afterward won't restore them, since the original value is no longer stored anywhere.
Does HyreTech tell me which rows it skipped?
Yes. Every row is validated on its own, bad rows are skipped and listed with a reason, and the good rows still import. The batch finishes as Completed, Partial or Failed. Re-uploading the corrected file updates in place without creating duplicates.